
The converter was never the hard part for migrating from MySQL.
Schema, indexes, and data convert with tooling. Views, triggers, and stored procedures need manual engineering, and on most MySQL migrations that sets the timeline. EDB Migration Toolkit supports MySQL 5.5, 5.7, and 8.0 as sources, with PostgreSQL or EDB Postgres® AI (EDB PG AI) as targets. EDB engineers can help with the parts that aren't automated.
Why teams move from MySQL
MySQL is free and open source, so this isn't a question of license renewal; the reasons for moving have to do with the workload you're building now and the roadmap you're building it on.
Where the engine difference actually is. InnoDB is a multi-version concurrency engine, so on an InnoDB estate concurrency is not the differentiator. The differences that change what you can build are in the query planner, the indexing options, JSONB, the type system, and the extension ecosystem—which is why reason one above is the one that tends to decide it.
What converts, and what is hand work
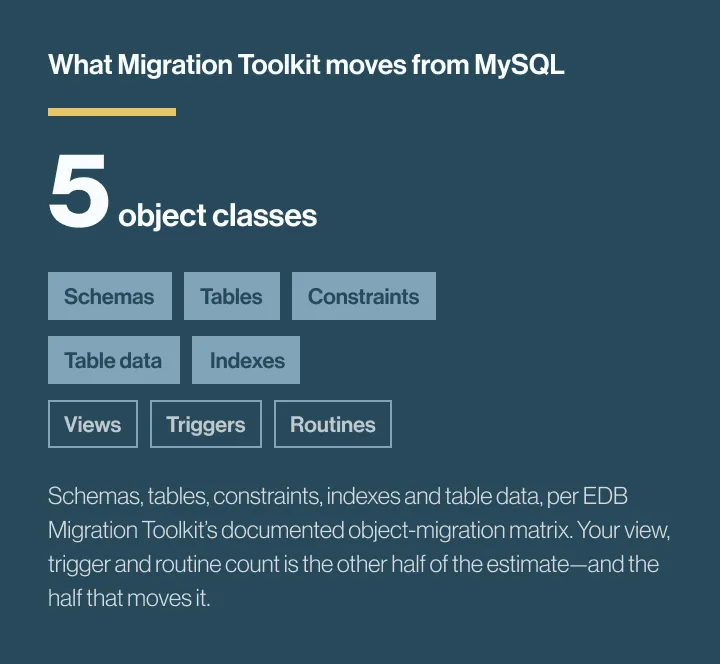
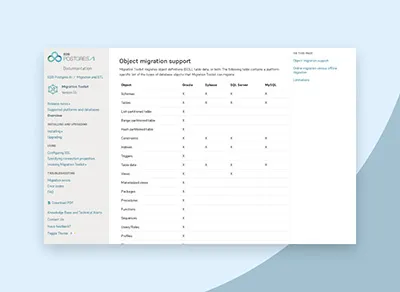
EDB Migration Toolkit supports MySQL 5.5, 5.7, and 8.0 as sources, with either community PostgreSQL or EDB PG AI as targets. Its documented object matrix covers five classes. Everything else is engineering effort, and an accurate count of it is what turns a migration from a guess into a plan.
Object class | Migration Toolkit | Note |
|---|---|---|
Schemas, tables, constraints, indexes, table data | Migrated | The relational skeleton and the rows. This part is largely mechanical. |
Views | Hand work | Not in the MySQL object matrix, and not converted by pgloader either; converting them would require a full MySQL dialect parser. |
Triggers | Hand work | Not automated by any tool in this space. |
Stored procedures and functions | Hand work | MySQL's procedural language and PL/pgSQL are not compatible. Each routine is a rewrite, or moves to the application layer. Usually the largest single line item in the estimate. |
Partitioned tables | Hand work | Partition schemes are redesigned rather than ported, which is often the right moment to revisit them anyway. |
Users, roles, and grants | Hand work | Plan the credential and access-control rebuild as a cutover task with its own security sign-off. |
Per EDB Migration Toolkit's documented object-migration matrix and pgloader's published MySQL limitations. Confirm against a schema assessment of your own estate.
The behaviors that surprise people
MySQL behavior | On Postgres | What it means for you |
|---|---|---|
Case-insensitive string comparison | Case-sensitive by default | The one that reaches production undetected. MySQL's common default collations match 'bob' to 'Bob'. Postgres does not. The same query returns zero rows and raises no error. Fix with citext, a lower() expression index, ILIKE, or a nondeterministic collation—but find it first. |
Non-strict mode | Values are validated | MySQL silently truncates over-length strings and coerces bad values. Postgres rejects them. Every row MySQL quietly accepted gets re-validated on load, which is why this surfaces late in the load rather than at the start. |
Zero dates (0000-00-00) | Not representable | pgloader converts them to NULL by default. A hand-rolled load needs a null-or-sentinel decision per column. |
Implicit type coercion | Most cross-type comparisons error | Comparing '123' to an integer column is fine in MySQL. These surface at runtime, not at schema validation, so schema-only testing gives false confidence. |
Unquoted identifier folding | Folded to lowercase | MyTable becomes mytable unless quoted—and if you quote, every application query must quote too. Backticks become double quotes. |
TINYINT(1) as boolean | boolean, or smallint | MySQL's de facto boolean. It may genuinely be a boolean in one table and a small integer in another, so the mapping is a per-column decision. |
AUTO_INCREMENT | Generated always as identity | Mechanical. SERIAL is the legacy form; identity is the SQL-standard one. Either way, reset sequences after load or your first insert is a duplicate-key error. |
Unsigned integers | No equivalent | Widen: int unsigned becomes bigint, and so on up the chain. |
Legacy utf8 (utf8mb3) | UTF-8 | A 3-byte encoding that can't hold emoji or four-byte CJK. Estates still on it may find data that was already lossy in MySQL. utf8mb4 maps cleanly. |
MyISAM tables | No equivalent—everything is transactional | MyISAM has no transactions and no foreign keys, so referential integrity was often enforced only in application code. Landing that in Postgres with real foreign keys will surface orphan rows. Better to know now. |
Behaviors as documented by the PostgreSQL project, pgloader's casting rules, and EDB Migration Toolkit's documentation. Some also depend on your MySQL server configuration—confirm against your own estate.
Where the work actually is
Schema conversion is solved. pgloader does it in one command—tables, indexes, foreign keys, sequences, parallel data load—and its casting rules already handle AUTO_INCREMENT, TINYINT(1), zero dates, unsigned widening and ENUM. Migration Toolkit covers the same ground with commercial support behind the result. Either way, that part is not where projects go wrong.
The first deliverable is a costed backlog, not a completed migration. Every view, trigger, and routine inventoried; every application query sorted into portable, needs syntax changes, needs a data-model change, or better replaced with a Postgres-native pattern. That backlog is the project plan. Everything before it is estimation by analogy.
How a migration runs, end to end
The same five stages, in the same order, wherever code and schema have to be converted.
Assess
Schema, object inventory and application SQL classification
Transform
Schema conversion; routines and views rewritten
Remediate
Behavioral differences, collation, constraint violations
Move
Bulk load, reconcile, reset sequences
Validate
Functional and performance verification under real load
Plan the cutover around a maintenance window. EDB's supported path for MySQL is Migration Toolkit, online or offline. EDB Migration Portal is Oracle-only; EDB Replication Server and EDB Data Migration Service do not list MySQL as a source. There is no first-party EDB change-data-capture path for MySQL today.
If your system genuinely cannot take a window, that's a stage-one design conversation: it means a third-party CDC tool running alongside Migration Toolkit, and it changes the shape and cost of the project. Raise it early and it's a design choice; raise it late and it's a replan.
Community Postgres or EDB Postgres AI?
Unlike some source platforms, MySQL can migrate to either, so this is an architecture decision rather than a formality, and for plenty of estates the right answer is community Postgres.
Community PostgreSQL
If what you need is the engine—better query planning, JSONB, extensibility, real constraint enforcement—and your team is comfortable owning HA, backup, and patching, this is a legitimate destination and EDB will help you get there.
EDB Postgres AI
The better fit when you want enterprise features, EDB-supported tooling, and a more opinionated operational stack around security, availability, and manageability—particularly if you're replacing capabilities that sat in MySQL Enterprise Edition. One limit to plan for: the Enterprise Postgres (Oracle Compatible) edition, which is the server Migration Toolkit targets, doesn't currently support the enum data type, so MySQL ENUM columns move to CHECK constraints.
EDB Postgres AI Distributed High Availability
For continuous write availability across regions. If you're running Galera or Group Replication today, this is the nearest equivalent—but it should not be the default answer for a MySQL migration, only the right one when the goal is genuinely active-active.
Build the target as an HA cluster first, then migrate into it. Streaming replication with Failover Manager or repmgr, and backup with Barman or pgBackRest. Cutting over into an architecture that is already resilient is materially less work than retrofitting resilience afterwards.
Three things to prove before go-live, in this order: backups complete, WAL archiving works, and a full restore plus point-in-time recovery has been tested on the target. Not assumed—tested.
BENCHMARKED
faster bulk load
faster row-by-row INSERT
faster average SELECT
If you're on a MySQL-lineage fork
MariaDB and Percona Server share MySQL's wire protocol and most of its behavior, so essentially everything on this page—the object matrix, the collation trap, the zero dates, the routine rewrites—applies largely unchanged.
Formal support is a narrower statement. EDB Migration Toolkit's supported-database list names MySQL, not MariaDB or Percona Server. In practice the conversion path is the same; contractually it isn't the same commitment. Tell us the distribution and version and we'll tell you exactly where you stand.
Where the migrated system runs
Self-managed
On your own infrastructure, on-premises, or in your own cloud accounts.
Hybrid Manager
One control plane across on-premises and cloud estates.
Managed platform
A managed service where EDB operates the platform and your team keeps the workload.
Take it to your team
Technical Migration
Playbook

Documentation

Get the remediation backlog costed
An EDB migration architect counts the views, triggers and routines, classifies your application SQL, and works through downtime tolerance and target fit with your team. You come out with a costed backlog and a scoped timeline you can take to a budget conversation.